GPT-5.4 Mini via SERV api
$1 per 1M input tokens ($6.00 per 1M output) source (opens in a new tab)
Usage
For: Low-cost agent workloads
Limits
- 400K context
- Prepaid credits
Includes
- Reasoning compiler included in price
API included
Coding · pricing
Choose OpenServ if you want to route existing OpenAI or Anthropic SDK agent traffic through a reasoning layer by changing one base URL and pay per token from prepaid credits.
Our own captures of each vendor's public pages. Click a frame for the full-size image.
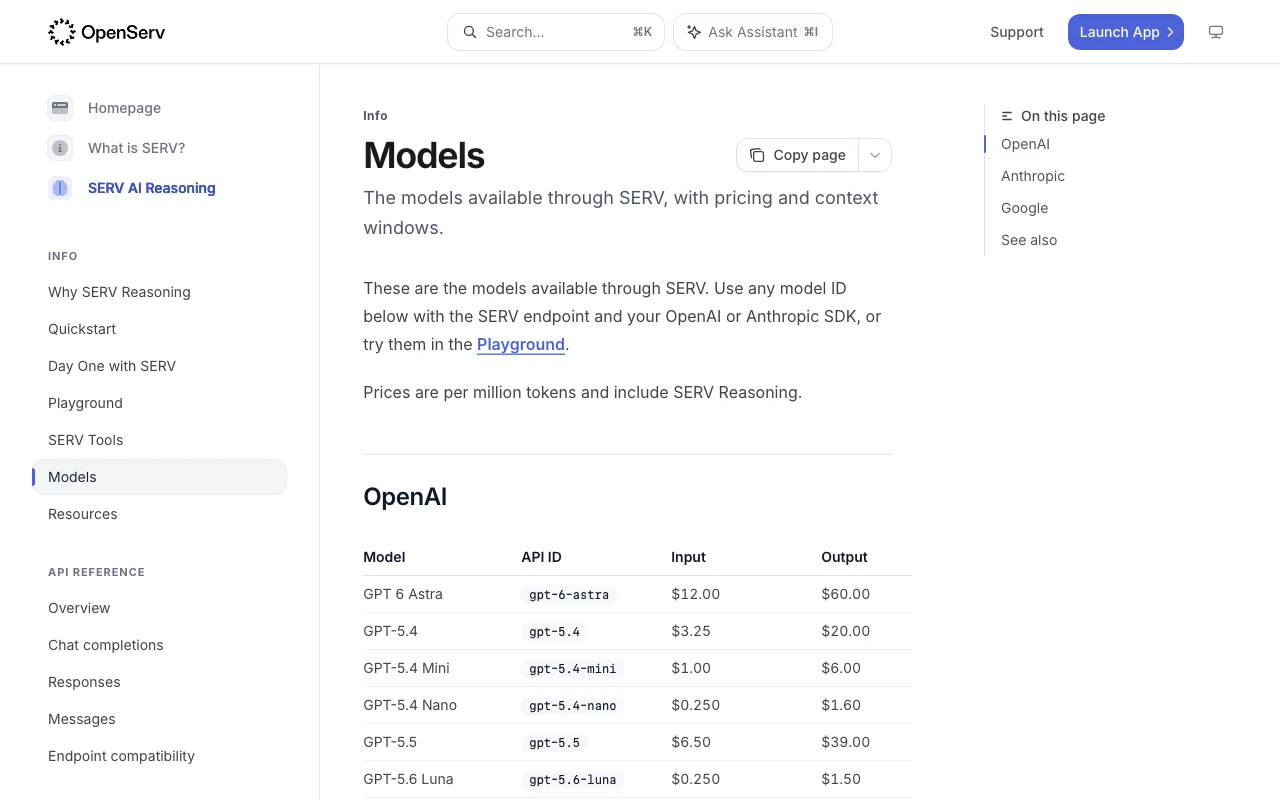
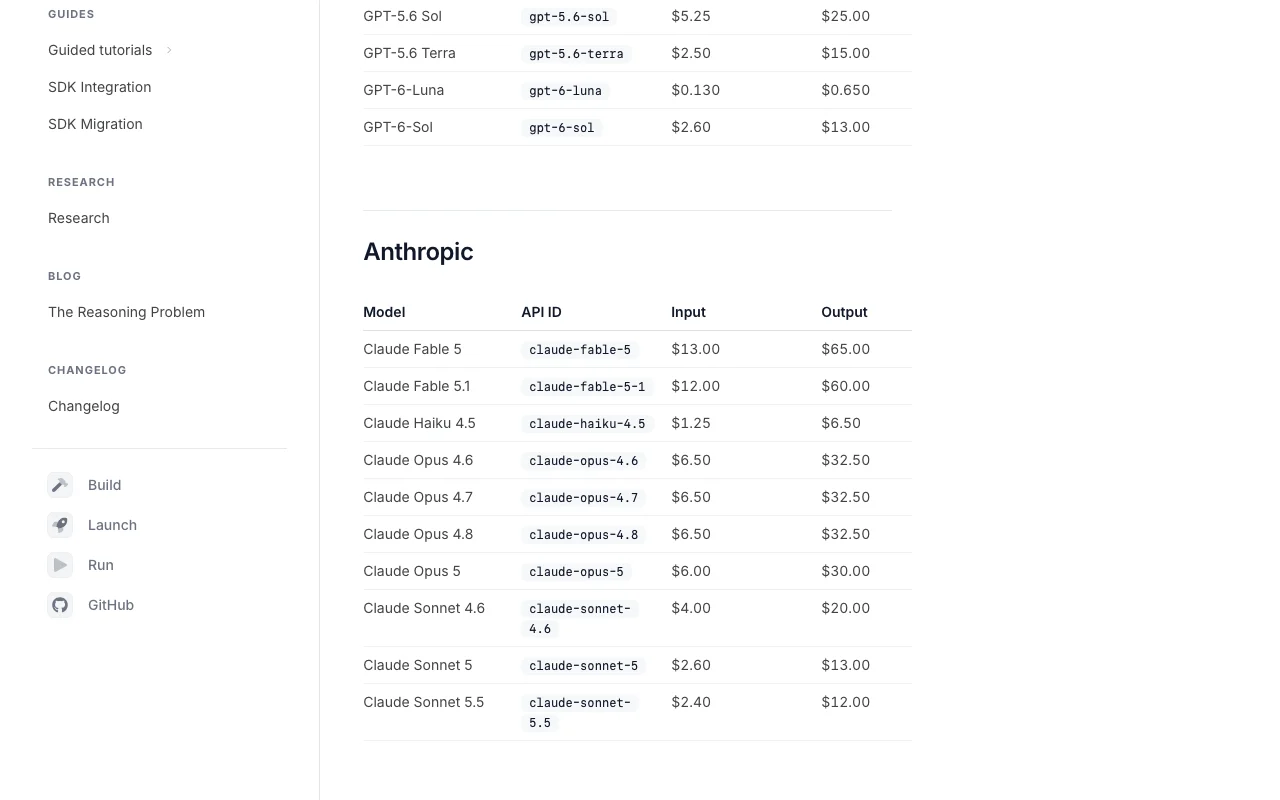
OpenServ does not have tiered plans. You buy prepaid credits and are billed per model at per-token prices, with the reasoning compiler included in the price. The three listed rates are GPT-5.4 Mini via SERV at $1 per 1M input tokens and $6.00 per 1M output (400K context), Claude Sonnet 5 via SERV at $2.6 per 1M input and $13.00 per 1M output, and Gemini 3.6 Flash via SERV at $1 per 1M input and $4.50 per 1M output.
No free tier is stated in our verified data. Because the SERV Reasoning layer is priced in, these rates differ from provider list prices. Prices checked on 2026-10-01.
| Plan | Price | Billing | Who it is for | Key limits | API |
|---|---|---|---|---|---|
| GPT-5.4 Mini via SERV api |
$1 per 1M input tokens ($6.00 per 1M output) | Usage | Low-cost agent workloads | 400K context; Prepaid credits | Included |
| Claude Sonnet 5 via SERV api |
$2.6 per 1M input tokens ($13.00 per 1M output) | Usage | Mid-tier Claude agents | Prepaid credits | Included |
| Gemini 3.6 Flash via SERV api |
$1 per 1M input tokens ($4.50 per 1M output) | Usage | Cheap fast calls | Prepaid credits | Included |
| If you | Pick | Why |
|---|---|---|
| you run low-cost agent workloads and want a large context window | GPT-5.4 Mini via SERV, $1 per 1M input | $6.00 per 1M output with 400K context, reasoning compiler included. |
| you want Claude models through an Anthropic-SDK-compatible endpoint | Claude Sonnet 5 via SERV, $2.6 per 1M input | $13.00 per 1M output; the mid-tier Claude option in the listing. |
| you need cheap, fast calls to Google models | Gemini 3.6 Flash via SERV, $1 per 1M input | $4.50 per 1M output, one API for Google models. |
No free tier stated.
Prices include SERV Reasoning, so they differ from provider list prices.
Prices checked Oct 1, 2026 on the official US pricing page. Official pricing ↗ Prices and limits change often.
Vendor pricing page re-checked automatically 13 days ago: no changes detected.
No free tier stated.
$1 per 1M input tokens ($6.00 per 1M output) source (opens in a new tab)
Usage
For: Low-cost agent workloads
Limits
Includes
API included
$2.6 per 1M input tokens ($13.00 per 1M output) source (opens in a new tab)
Usage
For: Mid-tier Claude agents
Limits
Includes
API included
$1 per 1M input tokens ($4.50 per 1M output) source (opens in a new tab)
Usage
For: Cheap fast calls
Limits
Includes
API included
Prices include SERV Reasoning, so they differ from provider list prices.
Per million input and output tokens by model, paid from prepaid credits; listed prices include SERV Reasoning. source (opens in a new tab)
Only organization owners can buy credits or manage billing, per the product pages. source (opens in a new tab)
No free tier is stated in our verified data. Usage is billed from prepaid credits.
$2.6 per 1M input tokens and $13.00 per 1M output tokens.
The listed rates include the SERV Reasoning compiler, so they can be higher than provider list prices.
Only organization owners can buy credits or manage billing.
compare>