DeepSeek pricing in 2026: API rates for deepseek-flash and deepseek-v4-pro explained
Choose DeepSeek when you want to call a 1M-context model through an OpenAI- or Anthropic-compatible API and pay per token, ideally scheduling heavy jobs off-peak.
Starting price
From $0.3 (deepseek-flash input (cache miss))
Free option
Yes
Plans
5
Prices checked
Oct 5, 2026
DeepSeek prices at a glance
DeepSeek's documented pricing is usage-based, not a subscription. The API charges per 1M tokens, with separate rates for input (cache miss), cached input and output. There are two models. deepseek-flash costs $0.30 per 1M input tokens and $1.20 per 1M output tokens at peak, and exactly half off-peak: $0.15 and $0.60. deepseek-v4-pro costs $1.32 input and $3.96 output at peak, or $0.66 and $1.98 off-peak. Peak hours are 01:00-04:00 and 06:00-10:00 UTC, Monday to Friday; every other hour, including weekends, is off-peak.
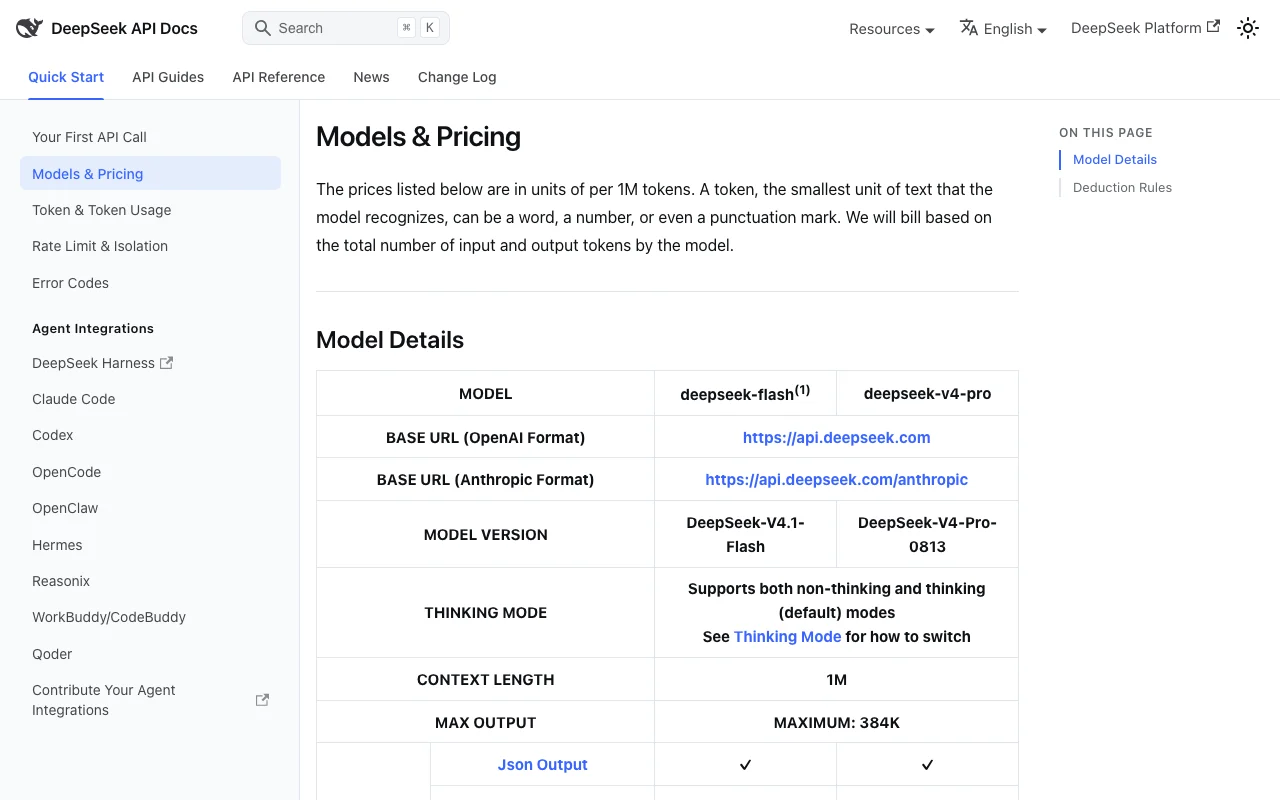
Cache hits are far cheaper than cache misses: for deepseek-flash, $0.006 per 1M input tokens at peak and $0.003 off-peak; for deepseek-v4-pro, $0.044 and $0.022. Both models list a 1M-token context and a 384K maximum output. The API deducts from a granted balance first, then from a topped-up balance. Whether the chat app is free, and what plans it has, could not be confirmed because the chat site blocked automated access, so no chat price is stated here.
DeepSeek plans compared
Plans and prices
Plan
Price
Billing
Who it is for
Key limits
API
deepseek-flash input (cache miss) API
$0.3 per 1M tokens
Per 1M tokens
Cost-sensitive API use
Peak hours 01:00-04:00 and 06:00-10:00 UTC Mon-Fri; Context 1M, max output 384K; Concurrency 2500
Included
deepseek-flash output API
$1.2 per 1M tokens
Per 1M tokens
Cost-sensitive API use
Off-peak is all other hours incl. weekends
Included
deepseek-v4-pro input (cache miss) API
$1.32 per 1M tokens
Per 1M tokens
Higher-capability API use
Vision not supported; Concurrency 500; Context 1M, max output 384K
Included
deepseek-v4-pro output API
$3.96 per 1M tokens
Per 1M tokens
Higher-capability API use
Off-peak is all other hours incl. weekends
Included
Chat app web
See official pricing
Unknown
General chat users
Not stated
Not stated
Which DeepSeek plan to pick
Which plan to pick
If you
Pick
Why
you want the cheapest API calls and can run jobs in batches
deepseek-flash, off-peak ($0.15 in / $0.60 out per 1M)
Half the peak rate, with vision, JSON output and tool calls. Concurrency is listed at 2500.
you need flash in interactive, time-of-day-bound use
deepseek-flash, peak ($0.30 in / $1.20 out per 1M)
Same model and limits at the full rate. Cache hits drop input to $0.006 per 1M.
you need the higher-capability model for heavy jobs
deepseek-v4-pro, off-peak ($0.66 in / $1.98 out per 1M)
Half the peak rate. Vision is not supported, and concurrency is listed at 500.
you need deepseek-v4-pro on a fixed schedule
deepseek-v4-pro, peak ($1.32 in / $3.96 out per 1M)
Full rate for the same model, with JSON output and tool calls. Cached input is $0.044 per 1M.
you only want to chat in the app
Chat app (price not confirmed)
Its free status and plans were not verified, so check the vendor's site before relying on it.
What is free, what costs extra
Free access and trial
Chat app free status not confirmed; the fetched chat site returned an error to the bot. The API deducts from a granted balance first, then a topped-up balance.
Not documented in fetched pages; granted balance is mentioned in deduction rules.
Extra costs and taxes
None listed beyond per-token usage; vendor reserves the right to change prices.
Not stated.
Costs that are easy to miss
Prices change with the clock: the same call costs double during weekday peak hours (01:00-04:00 and 06:00-10:00 UTC), so unscheduled traffic can cost up to twice the off-peak estimate.
Cache misses are billed at the full input rate; only repeated, cached input gets the lower cache-hit price.
The API is billed from a granted or topped-up balance, and the vendor reserves the right to change prices.
Taxes are not stated on the pricing page, and no extra fees beyond per-token usage are listed.
DeepSeek pricing and usage limits
Prices checked Oct 5, 2026 on the official US pricing page. Official pricing ↗ Prices and limits change often.
The official DeepSeek pricing page as we saw it. api-docs.deepseek.com, captured Oct 5, 2026
Free access and trial conditions
Chat app free status not confirmed; the fetched chat site returned an error to the bot. The API deducts from a granted balance first, then a topped-up balance.
Not documented in fetched pages; granted balance is mentioned in deduction rules.
None listed beyond per-token usage; vendor reserves the right to change prices.
Not stated.
DeepSeek FAQ
When does DeepSeek charge the lower off-peak rate?
Off-peak applies to every hour except 01:00-04:00 and 06:00-10:00 UTC on weekdays (Chinese public holidays count as off-peak), and costs half the peak rate. source (opens in a new tab)
What is the difference between deepseek-flash and deepseek-v4-pro?
Both have 1M context, 384K max output, JSON output and tool calls. Flash supports vision and is cheaper (peak $0.30 input cache-miss, $1.20 output); Pro does not support vision (peak $1.32 / $3.96). source (opens in a new tab)
How is the API billed?
Cost equals tokens times price, deducted from a granted balance first and then your topped-up balance. source (opens in a new tab)
Are the legacy deepseek-v4-flash model names still usable?
They are still accepted, but the old models are retired; requests are served by DeepSeek-V4.1-Flash and billed at the Flash price. source (opens in a new tab)
How much cheaper is DeepSeek off-peak than at peak?
Exactly half. deepseek-flash drops from $0.30 to $0.15 per 1M input tokens and from $1.20 to $0.60 per 1M output; deepseek-v4-pro drops from $1.32 to $0.66 input and from $3.96 to $1.98 output.
When are DeepSeek's peak hours?
01:00-04:00 and 06:00-10:00 UTC, Monday to Friday. All other hours, including weekends, are billed at the off-peak rate.
What does a cache hit cost on deepseek-v4-pro?
$0.044 per 1M input tokens at peak and $0.022 off-peak, versus $1.32 and $0.66 for a cache miss.
Is the DeepSeek chat app free?
Not confirmed. The chat site blocked automated access, so its free status and any plans are unverified; the documented prices cover the API only.